2026
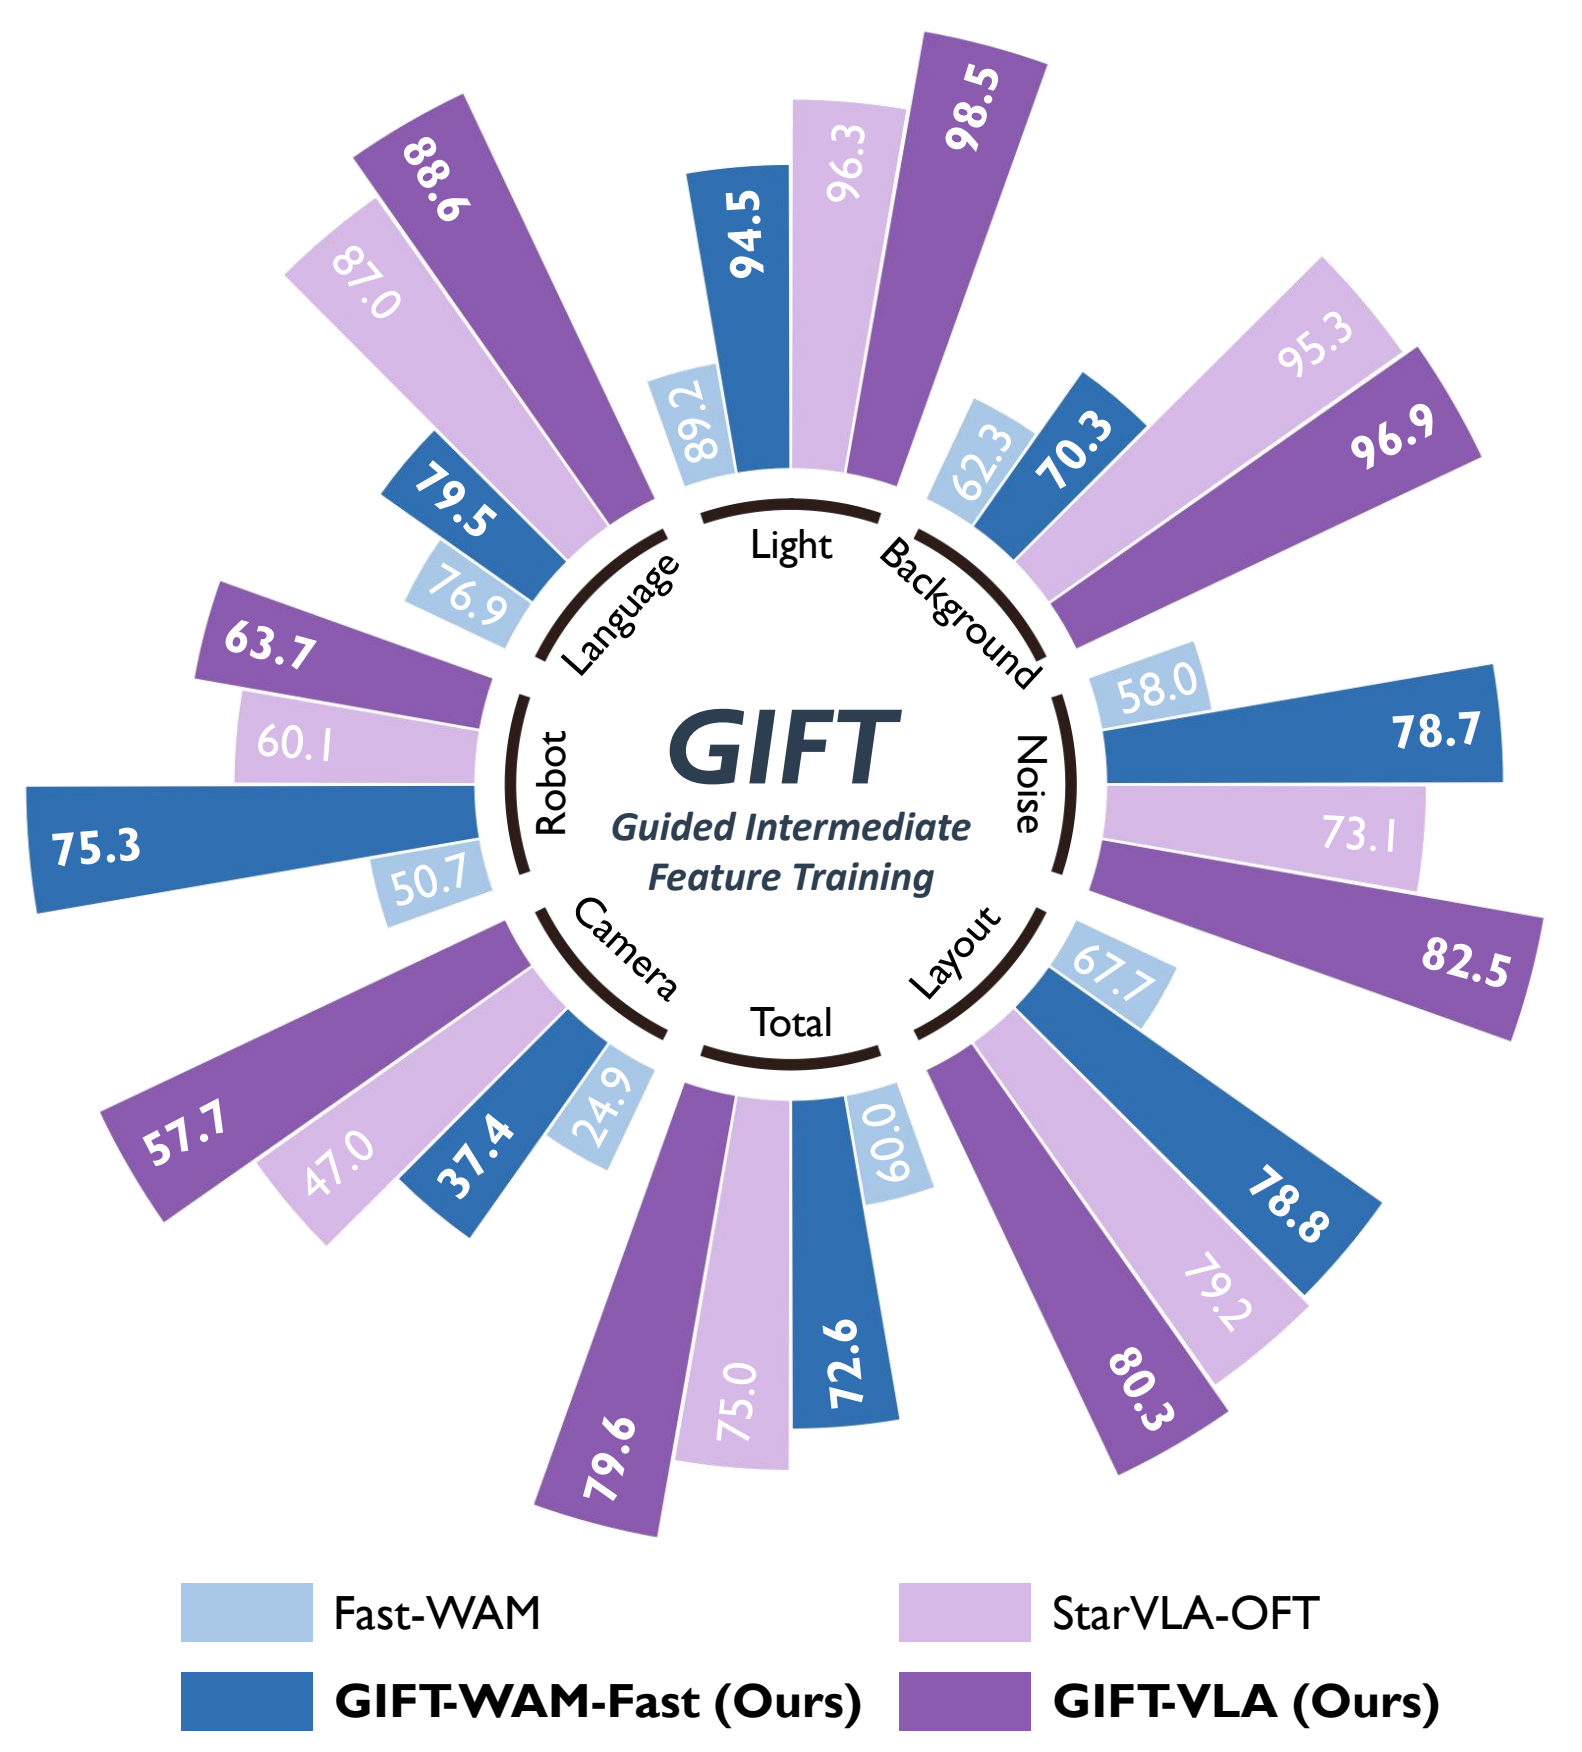
GIFT: Guided Intermediate Feature Training via Action-Oriented Structural Supervision for Robotic Manipulation
Yupeng Zheng*, Xiang Li*, Songen Gu*, Yuhang Zheng*, Shuai Tian, Weize Li, Linbo Wang, Chaoyue Li, Qichao Zhang, Haoran Li, Zhongpu Xia, Ya-Qin Zhang, Shuicheng Yan, Dongbin Zhao(* equal contribution)
Preprint 2026
GIFT guides intermediate features to preserve three control-relevant structures: geometry for motion feasibility, affordance for object-centric interaction, and goals for instruction-conditioned grounding. The same supervision principle transfers across a VLA and two WAM action formulations.
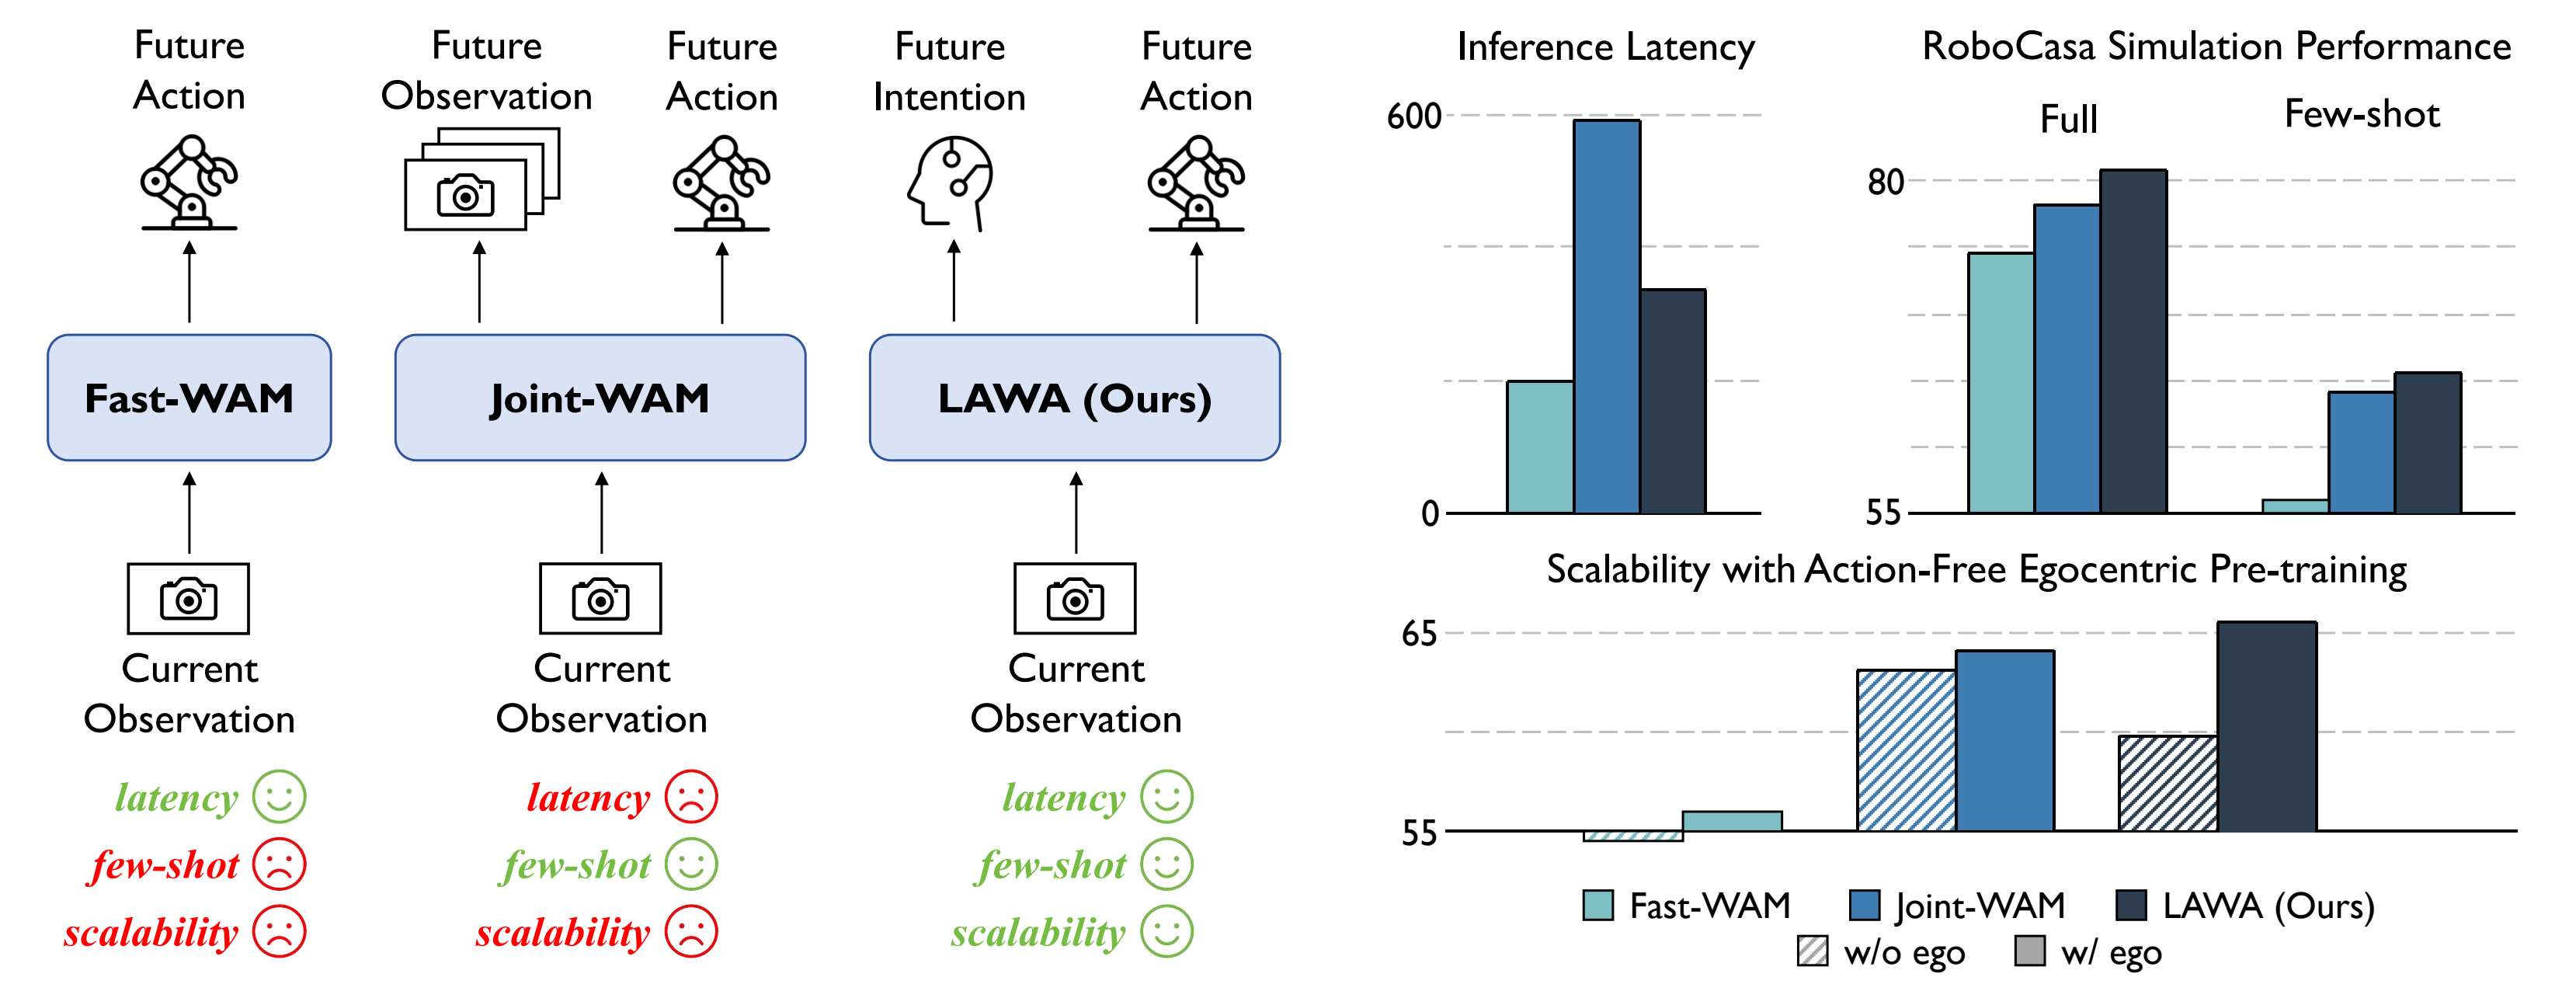
Latent Action as Intention Enables Efficient Future Imagination for World Action Models
Xiang Li*, Yupeng Zheng*, Songen Gu*, Huailiang Ma*, Feng Yu, Yuhang Zheng, Xian Nie, Shanshuai Yuan, Yujie Zang, Weize Li, Shuai Tian, Moyang Liu, Ya-Qin Zhang, Wenchao Ding(* equal contribution)
Preprint 2026
LAWA keeps the benefits of test-time future imagination for world action models while replacing expensive future-observation generation with compact latent intentions, yielding an effective trade-off among performance, generalization, and latency.
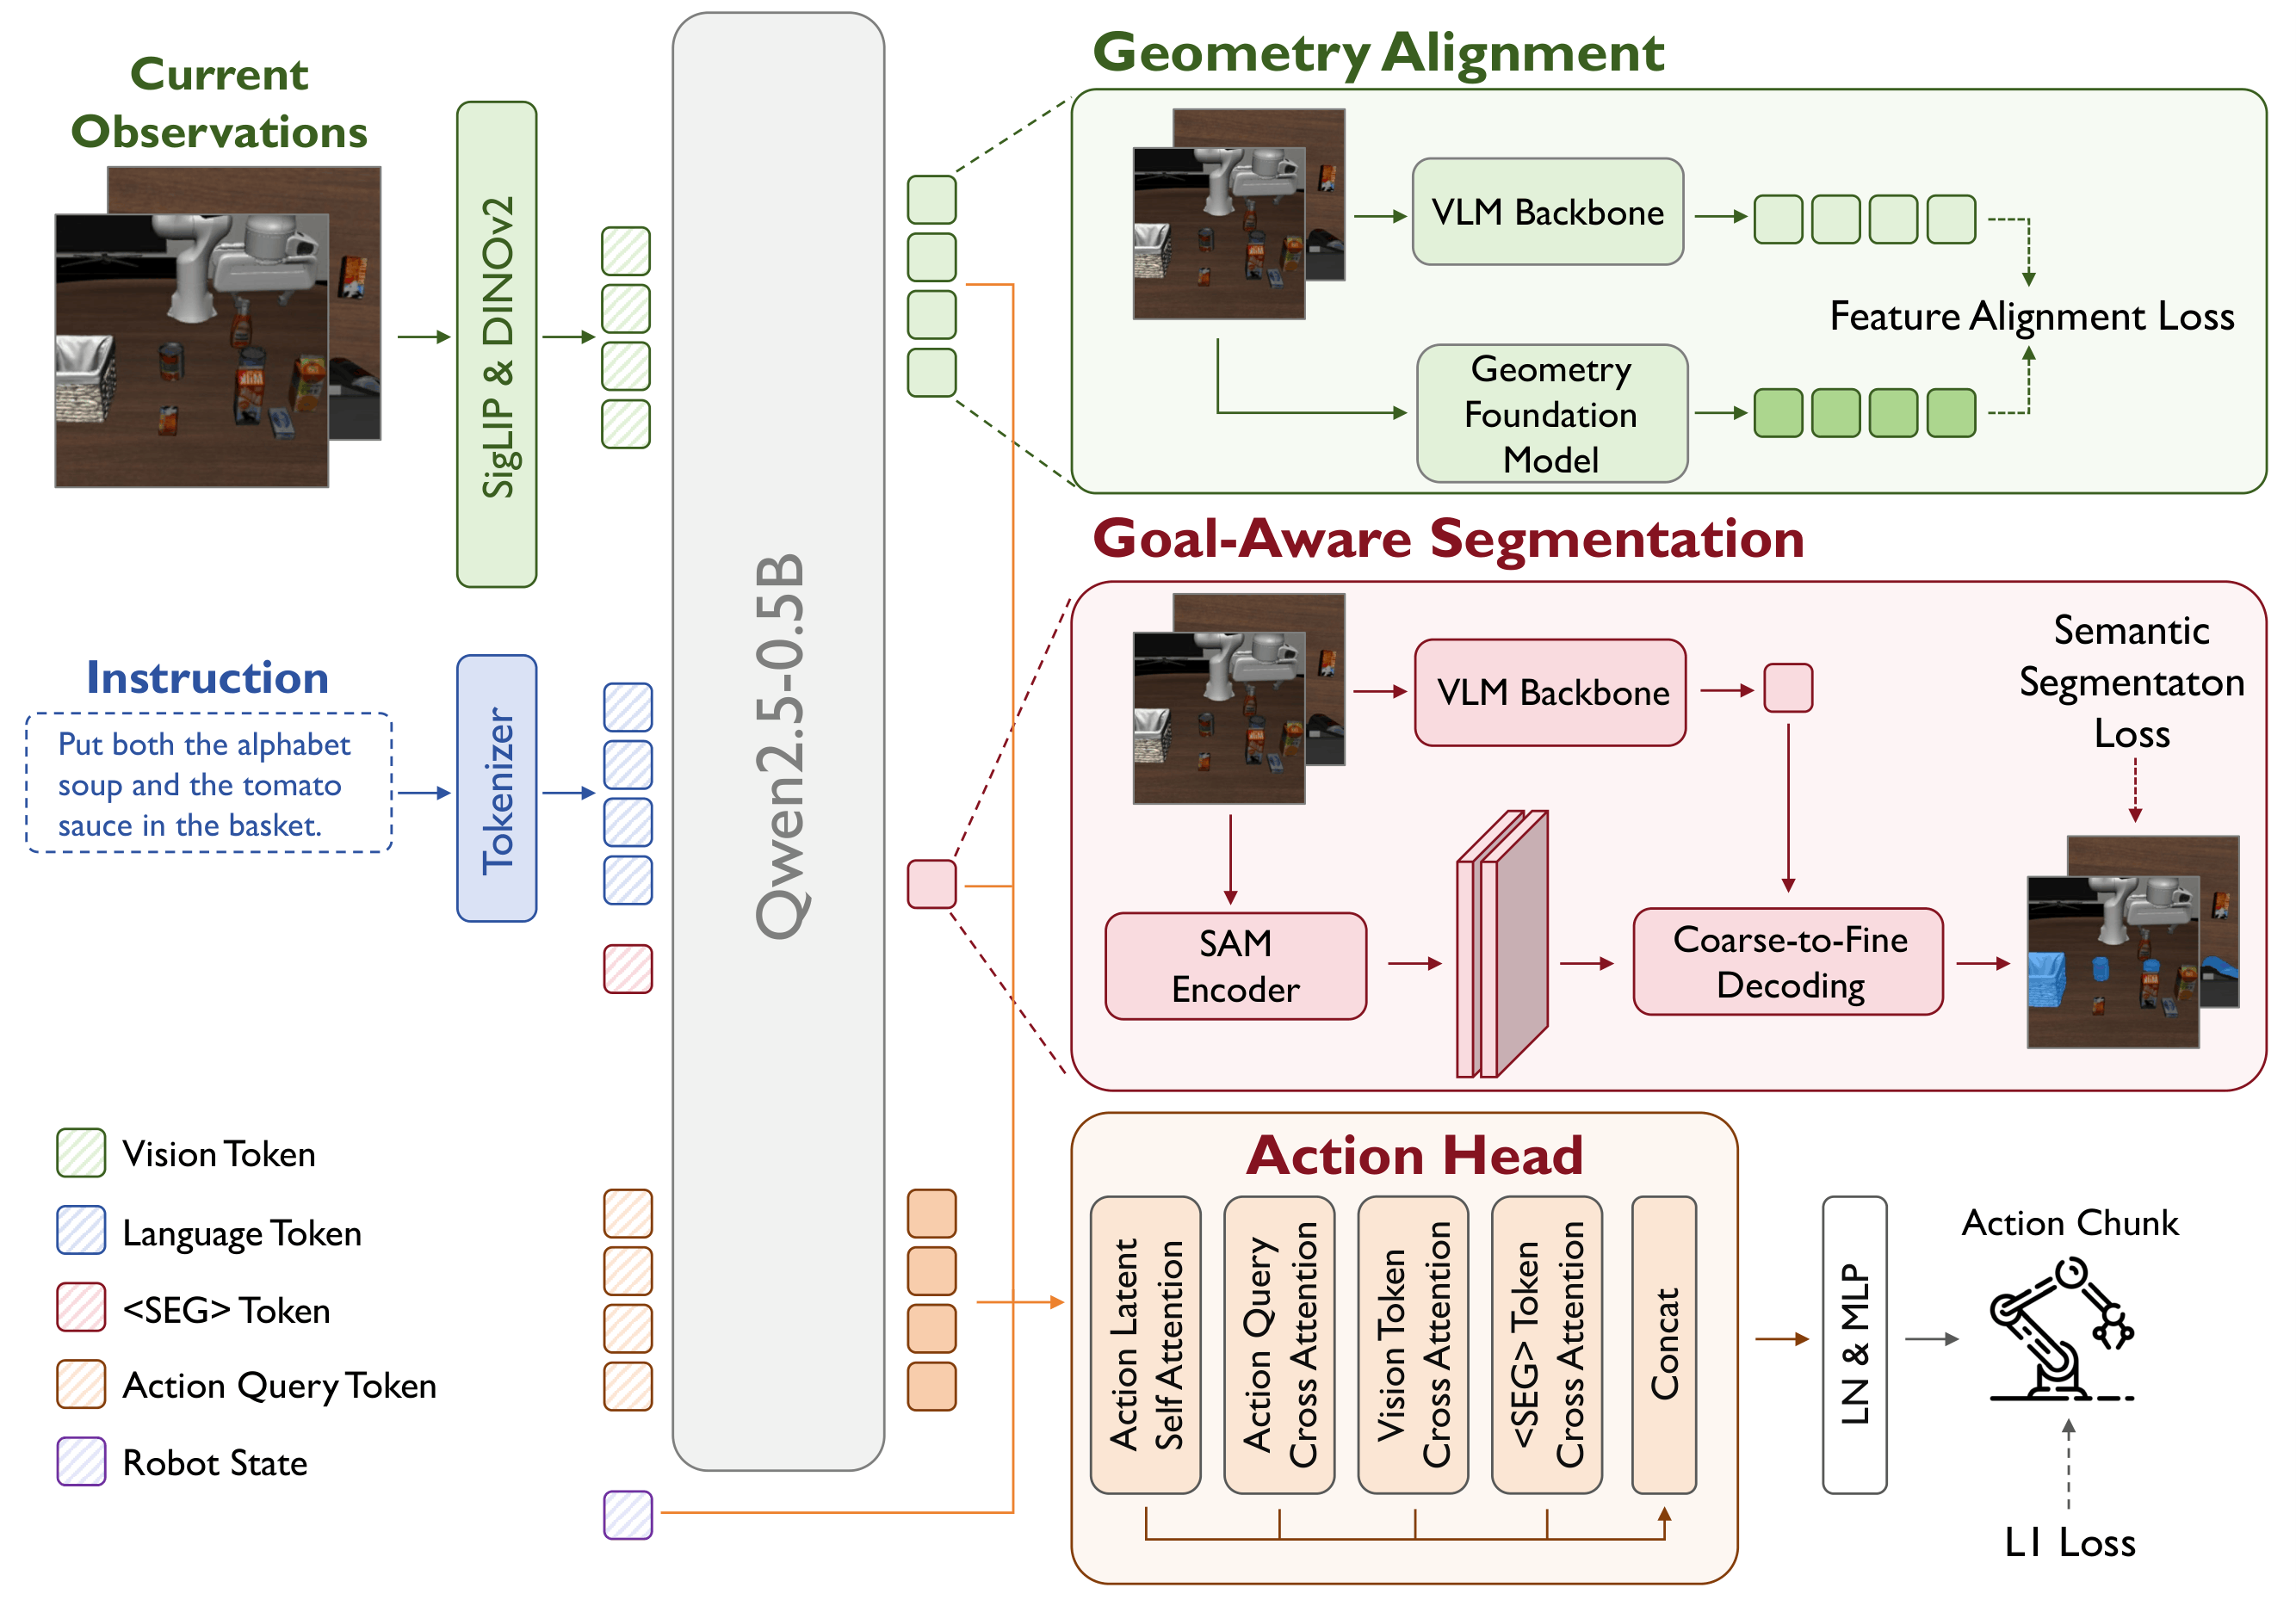
PokéVLA: Empowering Pocket-Sized Vision-Language-Action Model with Comprehensive World Knowledge Guidance
Yupeng Zheng*, Xiang Li*, Songen Gu*, Yuhang Zheng*, Shuai Tian, Weize Li, Linbo Wang, Senyu Fei, Pengfei Li, Yinfeng Gao, Zebin Xing, Yilun Chen, Qichao Zhang, Haoran Li, Wenchao Ding(* equal contribution)
Preprint 2026
We propose PokéVLA, a lightweight yet powerful foundation model for embodied manipulation that effectively infuses vision-language understanding into action learning.

OmniVTA: Visuo-Tactile World Modeling for Contact-Rich Robotic Manipulation
Yuhang Zheng, Songen Gu, Yupeng Zheng, Weize Li, Yujie Zang, Shuai Tian, Xiang Li, Ce Hao, Chen Gao, Si Liu, Haoran Li, Yilun Chen, Shuicheng Yan, Wenchao Ding
Preprint 2026
We introduce OmniViTac, a large-scale visuo-tactile-action dataset, and OmniVTA, a world-model-based framework that combines predictive contact modeling with high-frequency tactile feedback for robust contact-rich manipulation.